
1·
4 days ago

Shitposts abound, yo-ho-ho!
who said you’d need a gun for funnels?
nah mate. what you need… is this:

ein Flammenwerfer! Viel Spaß damit!
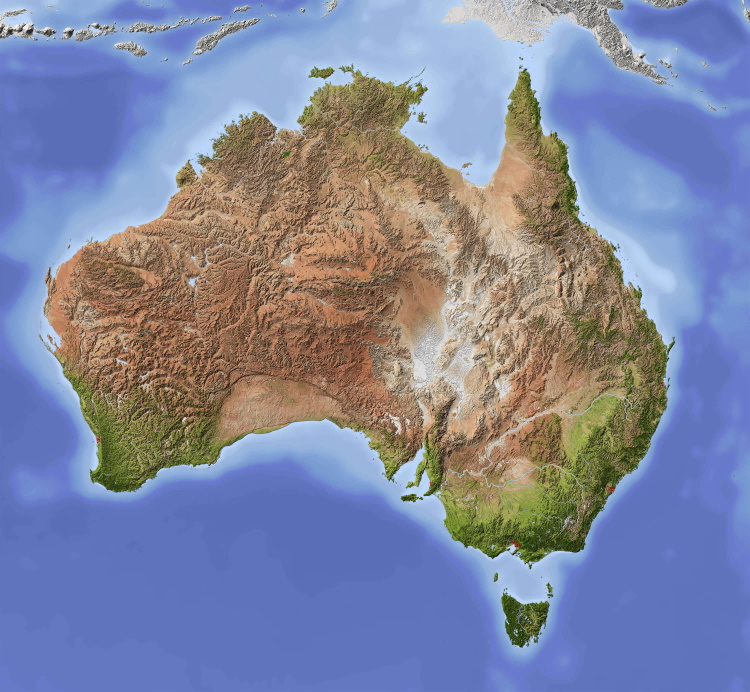
be me, Australian Continent
have the deadliest animals in the world
wildlife doesn’t care if the government says something, they still gonna fuck you up regardless
government wants to prevent its citizens from being able to protect themselves from said wildlife
absolutely genius move, can’t wait to see what your government does next!
first name: (boys) Lawrence, Marcus, Anthony, John/Jon(athan), Joe/Joseph, Zak/Zach(ariah; for non abbreviated), Sam(uel)
first name: (girls) Clara, Ainsley, Kelly, Vicky/Victoria, Audrey, Tanya/Tonya (depends on what region y’all are from),
twins: Terra (or Gaia)/Luna
thats all I’ve got. good luck, future dad.

you had my curiosity…
but now you have my erection attention.
would you kindly provide such sources, as to satisfy this curiosity?

I’ve not personally tested such stuff (as my setup is complete and I did the metadata all by hand before the age of LLMs), but to my understanding; the LLM is able to write opf/XML/whatever files you want for metadata, or even edit the file directly to add metadata. epubs and PDFs support author/title/etc tags iirc, so its not too hard to get the LLM to apply those after ingesting the text and searching online for matches.
I shitpost a lot in comments, making shitposts is lame and for losers. better to actually say meaningful things with a post rather than a nothingburger shitpost xD
I highly reccomend using calibre.
bonus points if you use a self hosted LLM to auto catalogue and apply metadata to the file before importing into calibre.
the recent openweight models are surprisingly good at reading files, pulling info, and doing simple monotonous tasks thousands of times without failing.
and thats where a self hosted llm comes in. feed it the files, have it apply the metadata, and bam you’ve got a library.
iirc calibre has a function like this now, its kinda cool IMO.
HELTER SKELTER IN A SUMMER SWELTER!
THE BIRDS FLEW OFF TO THE FALLOUT SHELTER
8 MILES HIGH AND FALLIN FAAAA–THEY LANDED HIGH, IN A CAST!
THE PLAYERS TRIED FOR A FORWARD PASS–

if you’ve got the spare time to wait for the open sign ups on myanonamouse, they’ve got an extremely extensive collection of rather rare ebooks.
if not, annasarchive and the sources on fmhy are very useful.

Allah ysalmak, akhi.
May your family be prosperous and happy.
~~*~I think I got that right, its been a while since I last studied my blessings…*~

If, by bible, you refer to the holy book of the local Building Code; then no, I have not.
and again; the regex in the script generated works, it’s just a teeny bit cursed and maybe a little bit sentient. Praise be to the Omnissaiah, and its blessed machine.
well, it works, and i don’t need to touch it.
remaking what is already working would cost more time.
regex is computationally pretty cheap, from what I’ve read; due to something about it being a simple AND gate or something… . IDR, and to be honest it doesn’t really matter in the era of 16-core/32thread 5GHz processors… but when you just want it to work… it does “just work”. /shrug.
it is a truly absurd number, simply due to the inane BS variations on terminology and notation.
It might have been more reasonable to train a local LLM on this material and then just query -that-… but hey 30ish seconds of claude’s free tier usage; and i’ve got a script that’s ~99.99% as good as a human in terms of pattern recognition. Pretty neat when you think about it.
My skillset is geared towards meatsacks and things that go boom. LLMs have been a massive boon to the 1% of my job that needs a code monkey.
As long as people still talk to each other, and things need exploding, I’ll have a job. Heck, if we somehow get to a point where money isnt needed, I’d still do what I do simply 'cuz I like it.
sweet merciful torvalds, that must have sucked.
Glad you made it out of that hellhole.
Not really. There will only ever be about a hundred people who ever use this tool, and it’s really just a massive timesaver that keeps people from needing to open a smorgasbord of files to get a few tidbits from each file; then collate it into one doc…
If I get ~99.99% of all the information, and one hundred people use this, odds are, nobody will ever see the .01% edge case of missed info. and even if it does happen, it’s not like it’s obsfucated information in each file, it’s just a pain to open a hundred files and wait for them all to load at once through the disk-heavy GUI application we have to use.
simpler to just read via the regex patterns, and then put it out into the terminal for the info needed.
